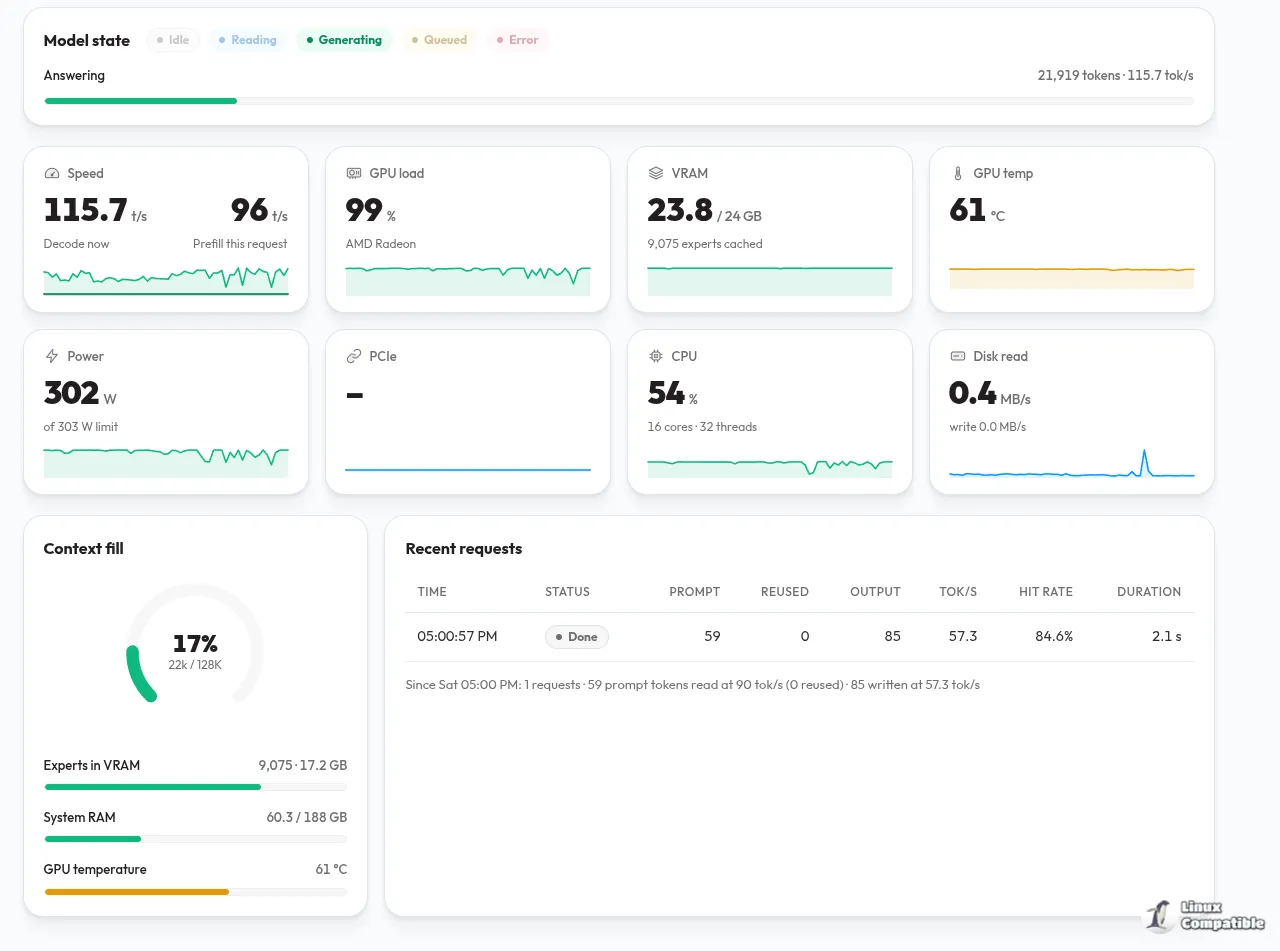
Strata v0.1.39 has been released, enhancing the speed of the local inference engine for the 125-billion-parameter Qwen3.8-Flash-Next model without altering the output, ensuring byte-identical responses to version 0.1.38. This update introduces features such as optional multi-GPU offload, parallel request handling, and compatibility with the OpenAI Responses API, making it easier for developers to utilize. It extends support to older hardware, including certain NVIDIA, AMD, and Intel GPUs, while achieving meaningful performance improvements primarily for RTX 20-series cards and above. Overall, Strata is positioned as a strong local AI solution, particularly for users with compatible hardware, while maintaining a focus on correctness and extensive validation
Strata v0.1.39 Runs 125B Local AI Faster Without Changing One Byte
Strata v0.1.39 makes the MIT-licensed local inference engine for the 125-billion-parameter Qwen3.8-Flash-Next model decode faster while keeping output byte-identical to 0.1.38. The update adds opt-in multi-GPU offload, parallel request handling, and an OpenAI Responses API so Codex CLI can drive a local instance. It also extends life to abandoned hardware, including Pascal and Volta NVIDIA cards, older AMD GPUs, Intel Arc, and CPUs without AVX2. Real-world gains are meaningful for RTX 20-series cards and up, though the older-gpu and experimental paths are compile-checked but not tested on actual hardware.
Strata v0.1.39 Runs 125B Local AI Faster Without Changing One Byte @ Linux Compatible